Make the physical world learn
We turn laboratories, engineering facilities, and factories into continuously learning systems.
The intelligence behind physical progress is distributed across experts, instruments, machines, software—and decades of trial and error. Yet most of it remains invisible to AI, and too much disappears when the work ends.
Iteria brings that intelligence into the learning loop. We train foundation models and agents on the complete trajectory of physical work: what people and machines observe, the actions they take, what fails, and what ultimately changes the outcome.
By connecting digital reasoning with physical execution, we are building one intelligence foundation across science and industry—so every experiment and production run can make the next one smarter.
Our north star is to accelerate invention 1000×.
From models to machines
Systems from our team that perceive, reason, act, and learn across digital and physical environments.
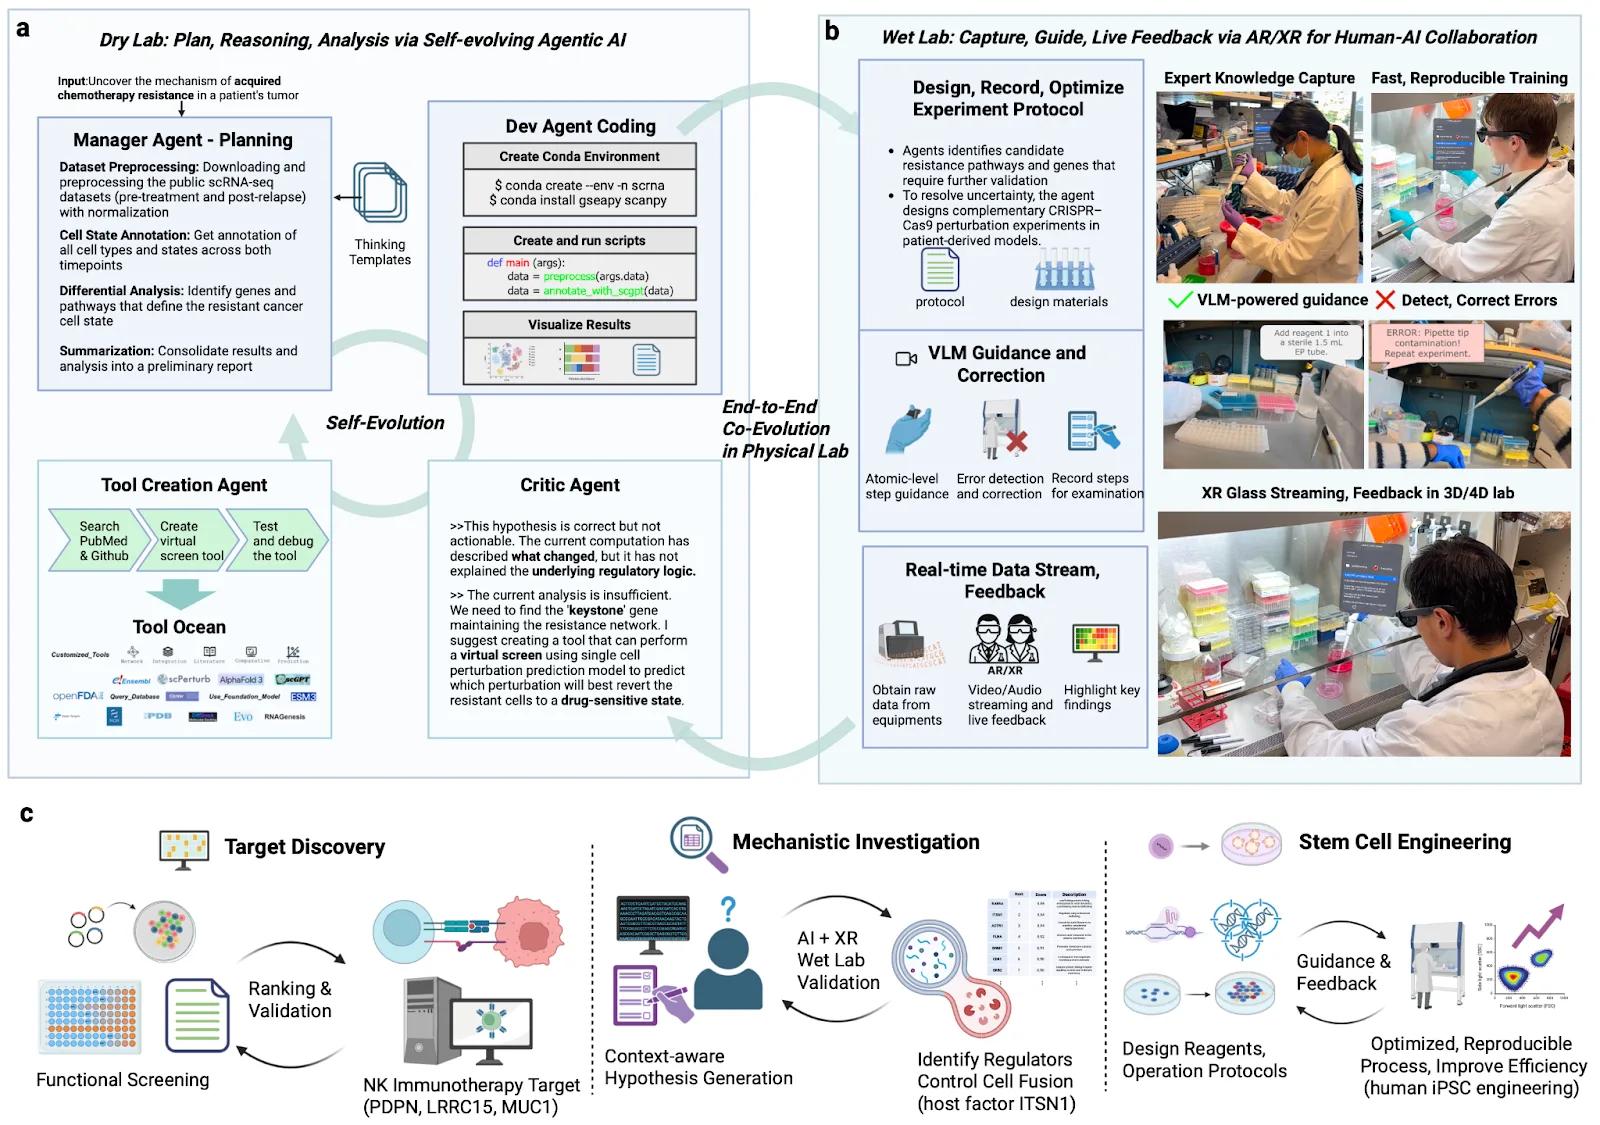
LabOS ↗
LabOS is an AI–XR co-scientist that connects scientific reasoning to physical experiments through multimodal perception, human collaboration, and robotic execution.
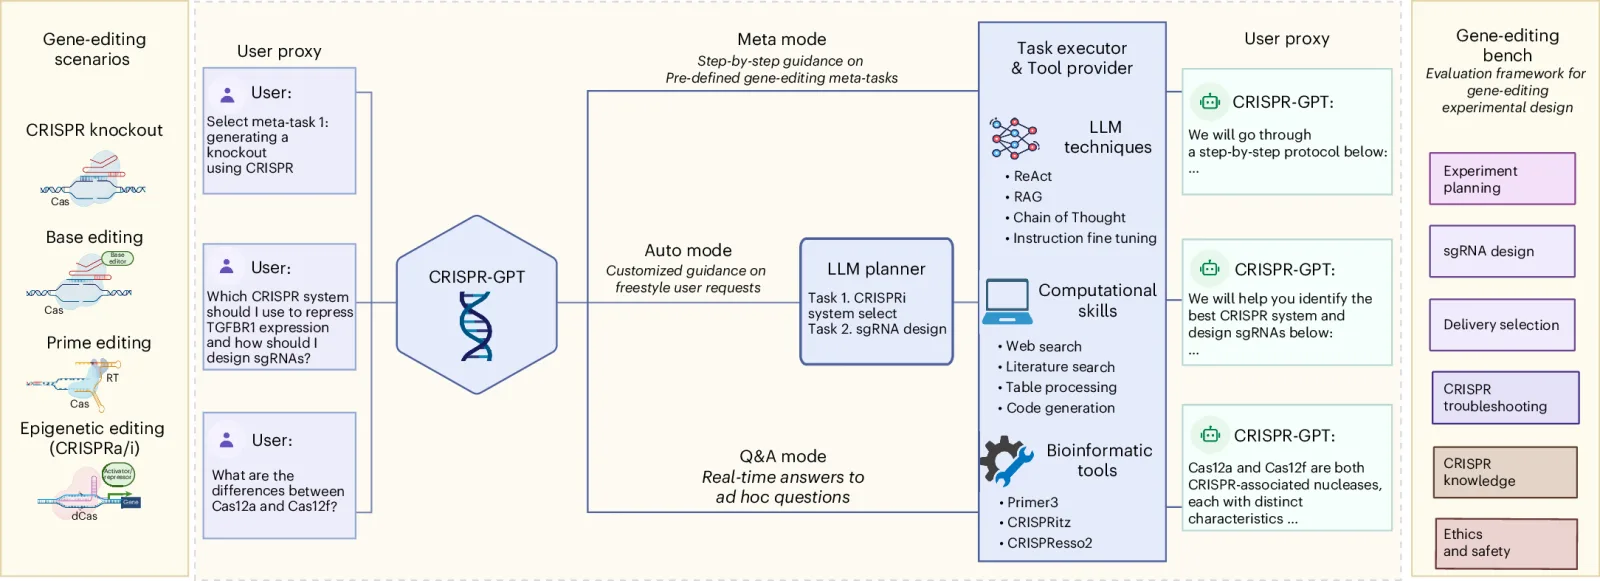
CRISPR-GPT ↗
CRISPR-GPT plans and guides gene-editing experiments, bringing domain knowledge, reasoning, and specialized tools into an end-to-end research workflow.
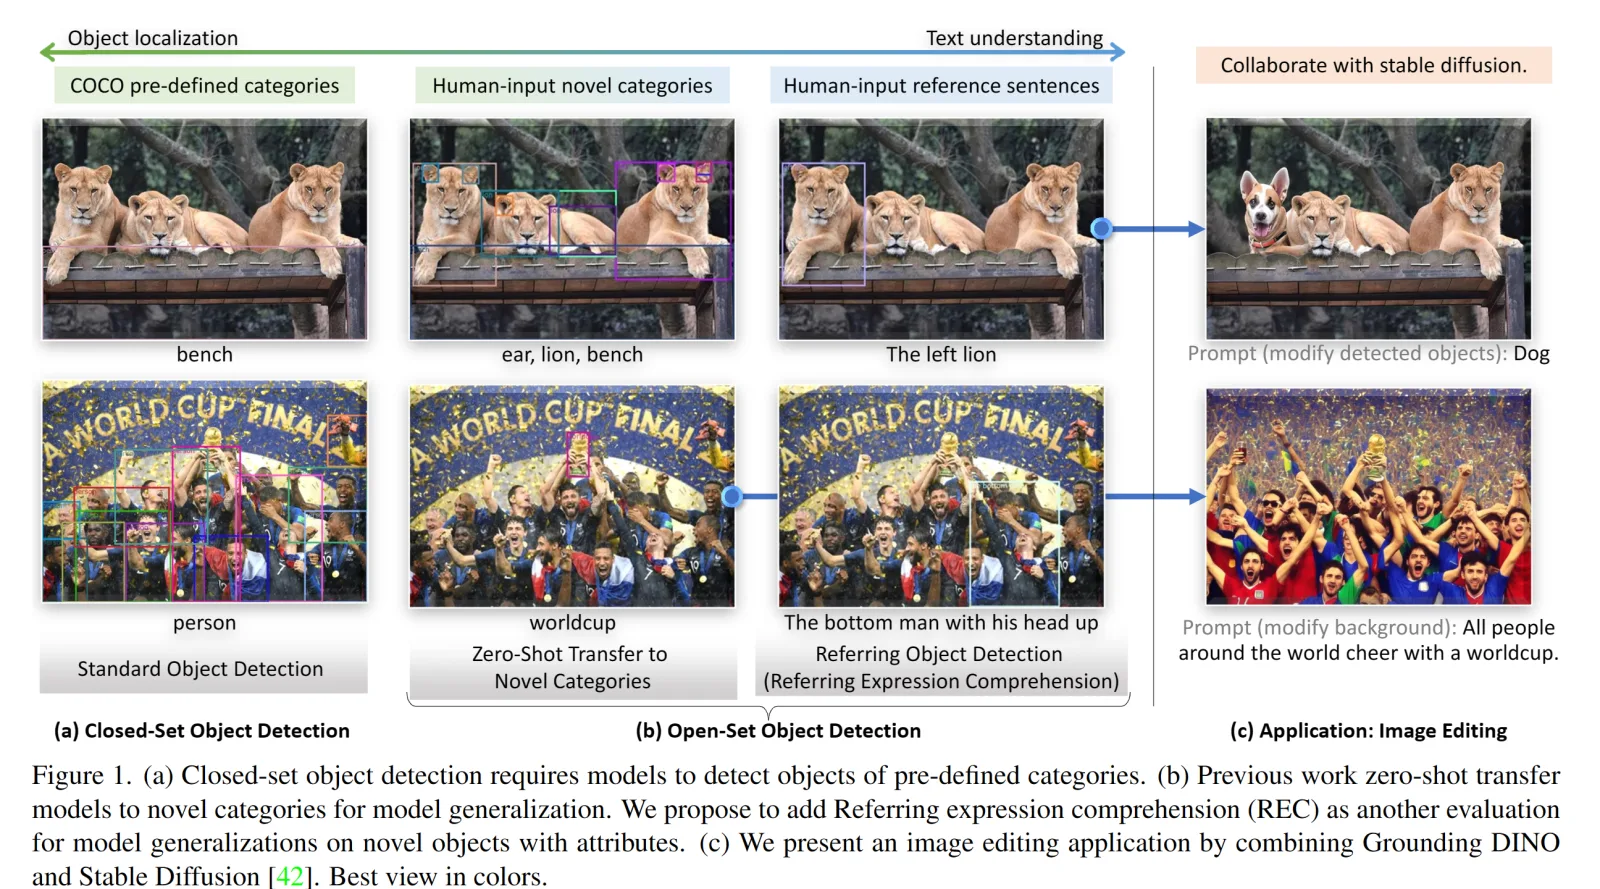
Grounding DINO ↗
Grounding DINO locates objects from natural-language prompts through open-vocabulary detection and has become a widely used foundation for open-world visual perception.
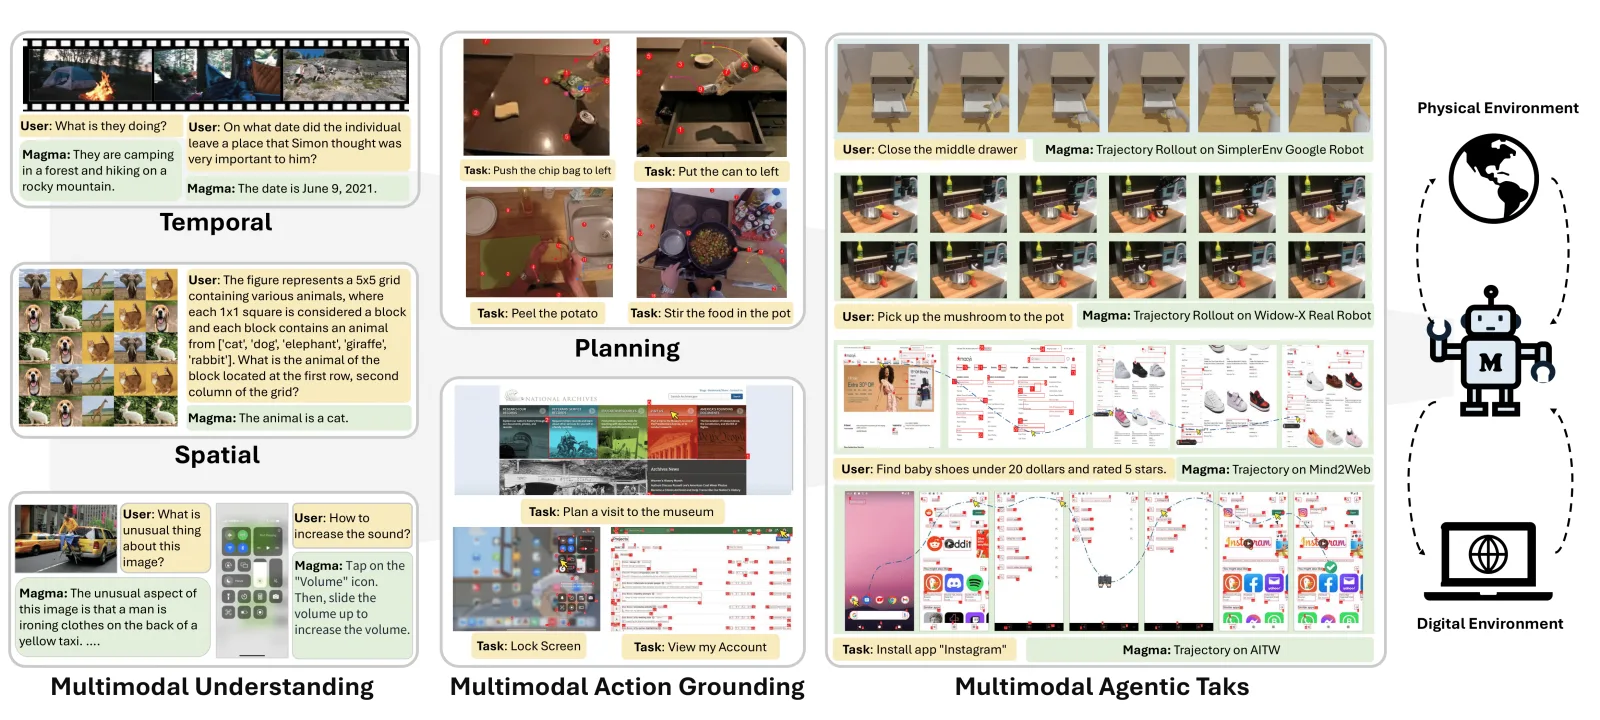
Magma ↗
Magma is a foundation model for multimodal agents that can understand and act across digital interfaces and physical robots.
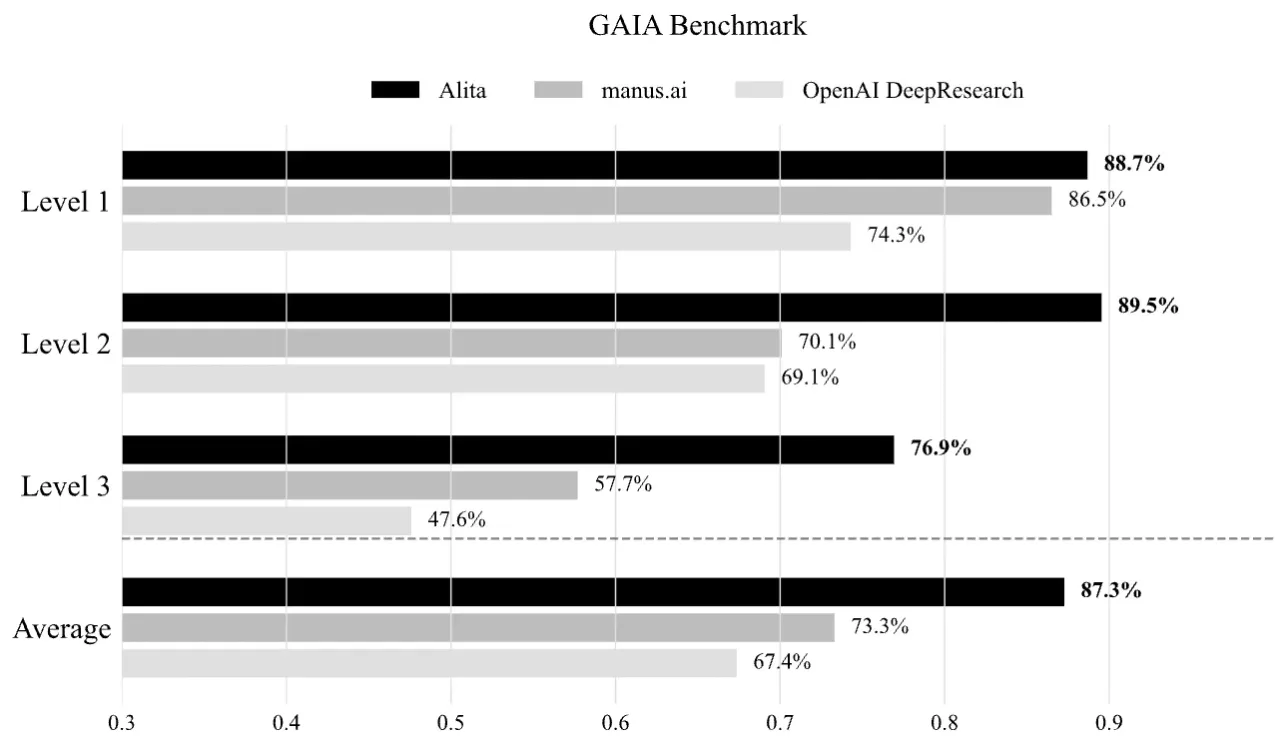
Alita ↗
Alita is a generalist agent designed to create tools and expand its own capabilities with minimal predefinition.
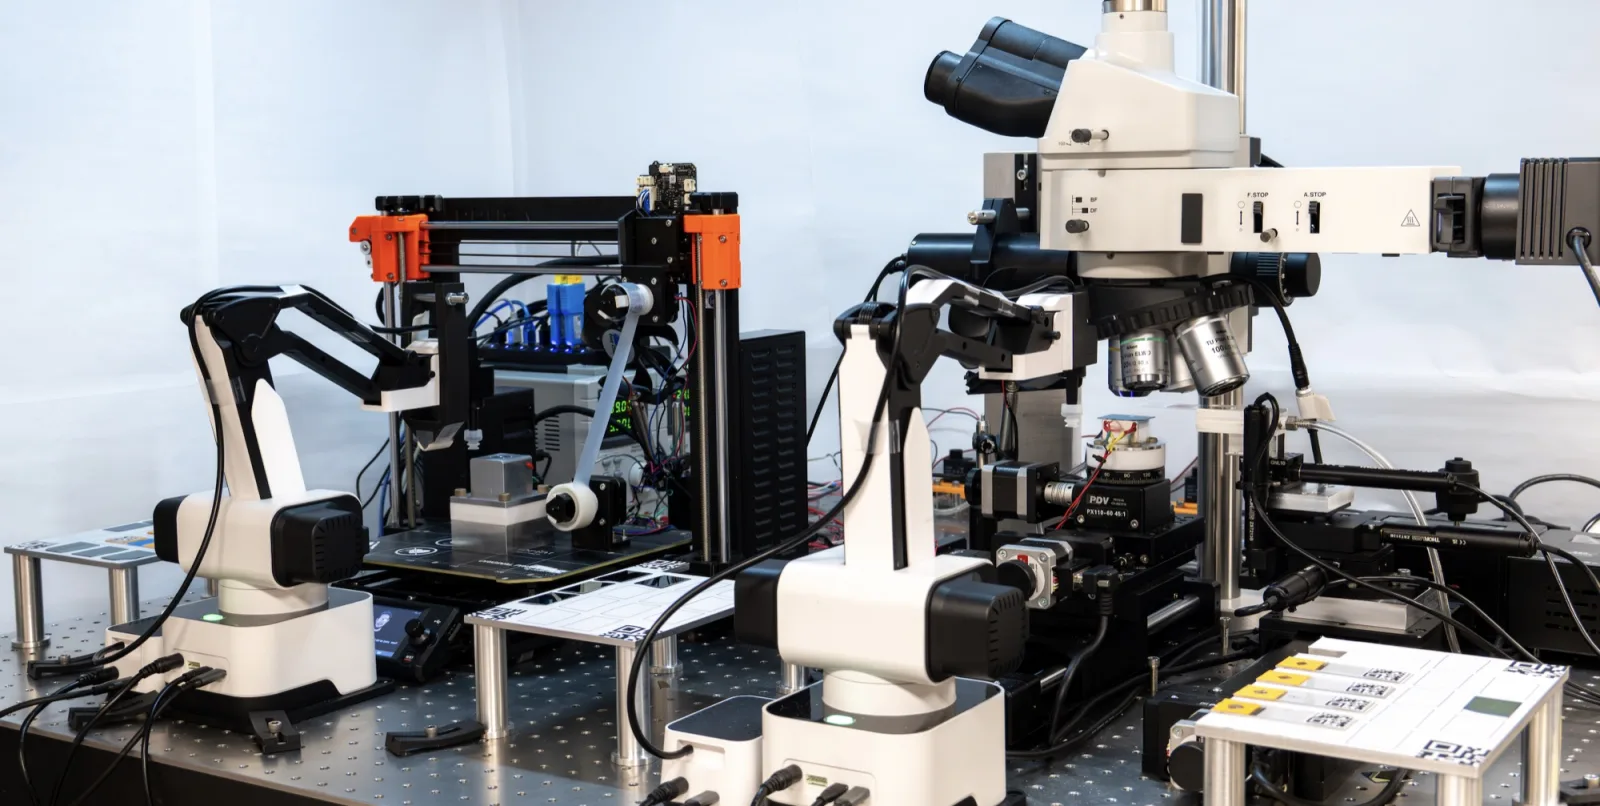
Qumus ↗
Qumus is an embodied AI experimentalist that closes the loop from hypothesis and protocol planning to physical experimentation in quantum materials.
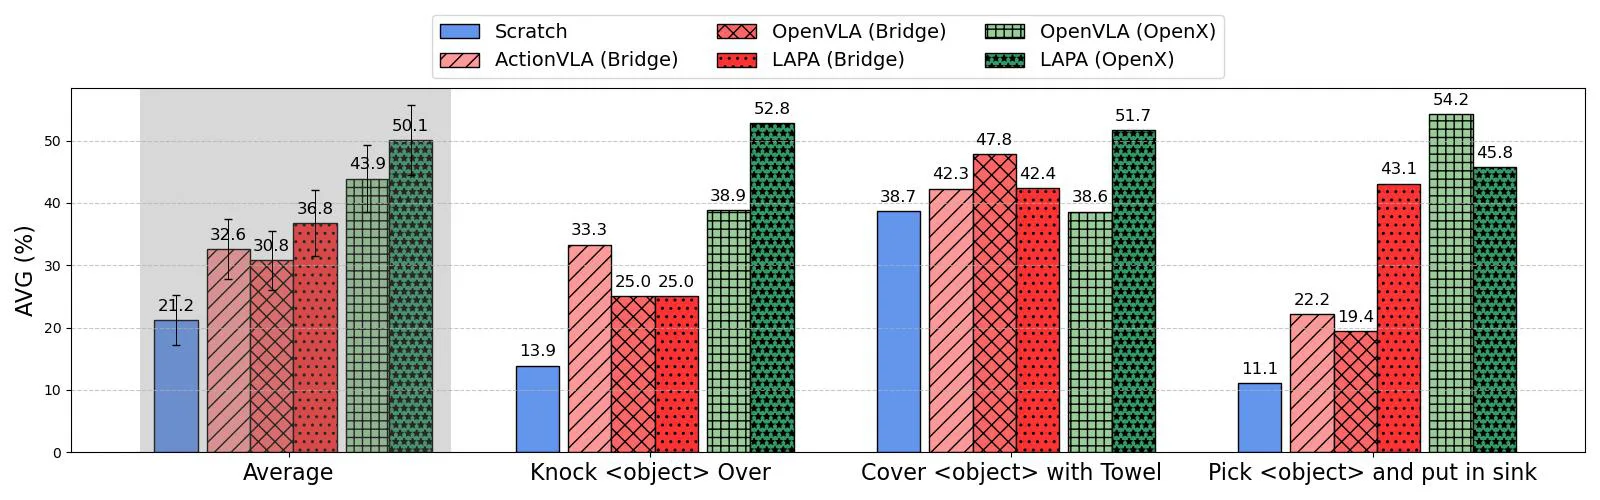
LAPA ↗
LAPA pretrains vision-language-action models from videos without requiring labeled robot actions, opening a new path for action learning.
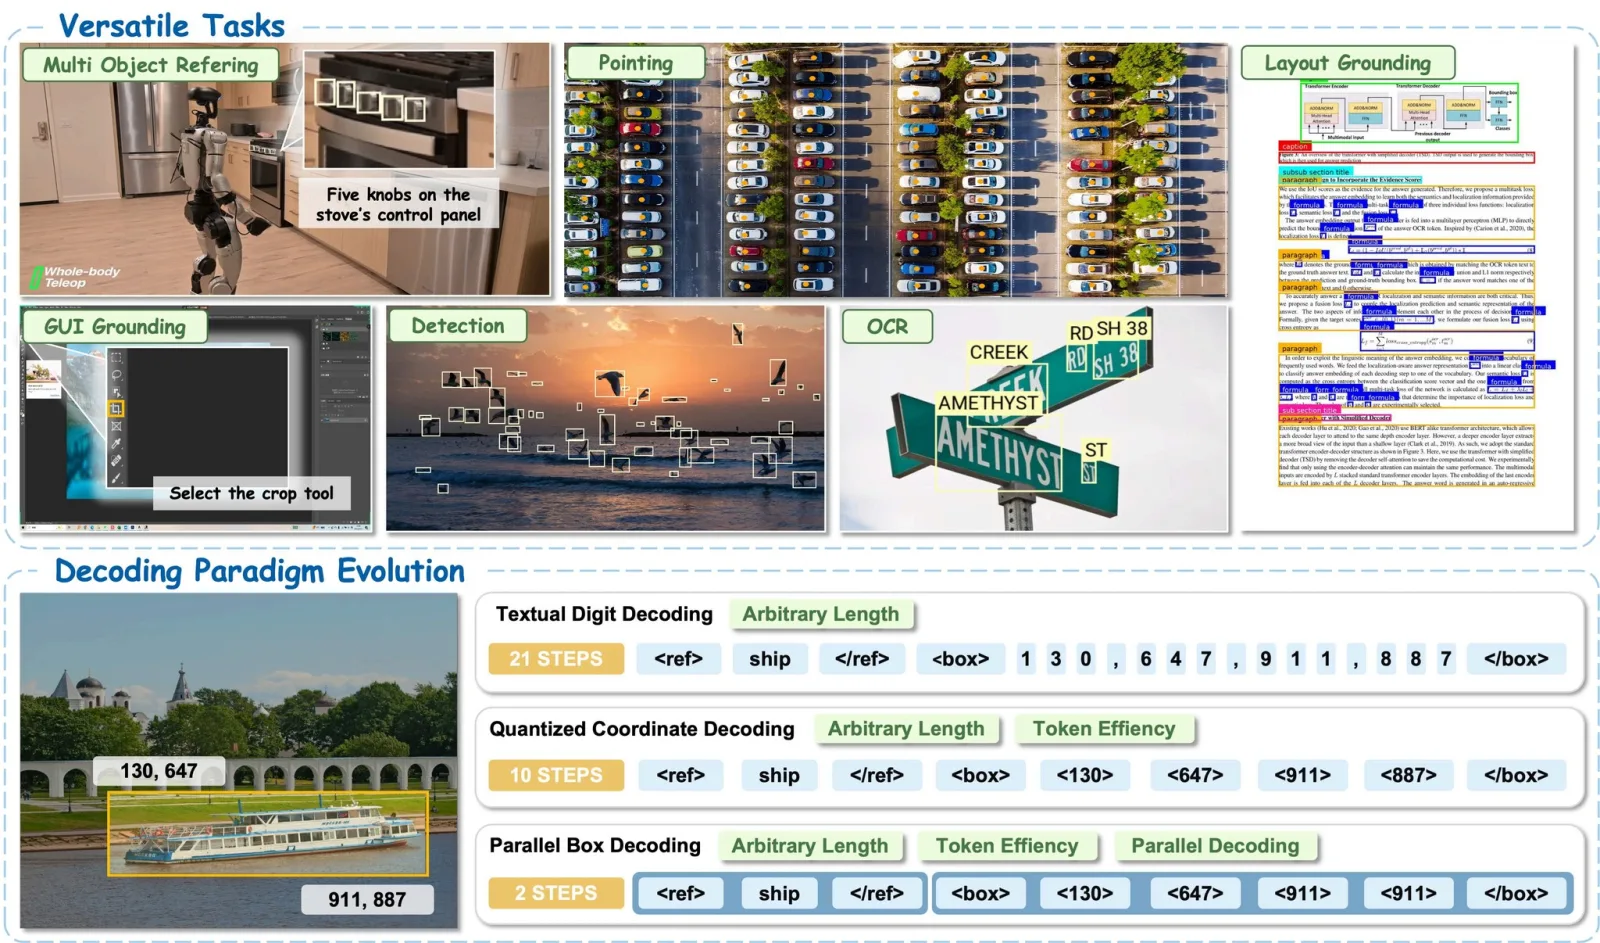
LocateAnything ↗
LocateAnything is a compact vision-language model for fast, precise localization across robotics, industrial scenes, interfaces, documents, and other complex environments.
First to the frontier
We bring together the people building frontier models with the scientists putting them to work in the physical world.
Iteria brings together researchers and builders from Princeton, Stanford, NVIDIA, and frontier AI labs. Our work spans foundation models, multimodal reasoning, embodied intelligence, robotics, and scientific discovery.
Members of our team developed frontier language and vision models, multimodal agents, world models, self-evolving agents, and visual foundation models. Together, we are building systems that perceive, reason, act, and learn across digital and physical environments.
Invent with us
Join the team—or become a design partner—and help turn physical innovation into a continuously learning system.
Join Iteria to build foundational AI for the physical world—or partner with us to shape it inside semiconductors, advanced manufacturing, and life sciences.